Some business software needs a judgment, not a conversation. It needs to know which team should receive a request, whether a document contains a required condition or which candidate result is most relevant. A decision model returns a constrained answer that code can use, rather than drafting a paragraph that another program must interpret.
TypeSafe's new Jev model makes that approach worth examining. The important distinction is not that confidence scores make automation infallible. It is that an explicit decision interface can make uncertainty and fallback behaviour easier to design.
Research window: 20 August to 19 September 2026. Jev's launch article is dated 14 September; the main Hacker News discussion began on 15 September. This guide is based on published sources, not an independent benchmark or a claim that D4J has deployed the example below.
What is Jev, and what was announced?
In its launch article, TypeSafe introduces Jev as its first “System One” model, available through early access. The company describes a model designed for structured, probabilistic decisions rather than free-form text generation.
The practical idea is straightforward: provide the relevant state, define the question and its allowed answer structure, then let ordinary code decide what happens next. The model contributes a judgment inside the application. It does not need to control the whole workflow.
This is not a universal replacement for a language model. A business may still want a generative model to draft correspondence or explain a document. A narrow decision component could sit beside it, helping choose a route or flag something for review. The right combination depends on the job.
TypeSafe publishes strong speed and cost claims, but also explains important limits of its evaluations. Its workflow tests were built by its own team and use other models' predictions as reference probabilities. The company notes possible bias and says its headline gains may be towards the high end of real-world results. Treat those figures as vendor evidence to investigate, not savings to place in a client proposal.
Which business tasks are a good fit?
A useful candidate has a defined question and an answer that changes a bounded part of the process. Examples include suggesting the correct support queue, identifying whether a message asks about a cancellation, or selecting relevant passages from a set of retrieved documents.
Start by distinguishing interpretation from exact rules. If a customer has already selected “billing” in a reliable form field, a routing rule may be enough. You do not need a model to rediscover that selection. If the request arrives as varied free text, a semantic judgment may add value.
The decision also needs a useful uncertainty route. If every ambiguous case must be forced into an ordinary category, the interface can hide the very uncertainty you wanted to manage. Include an appropriate no-match option, or a separate check for missing evidence, when the task requires it.
Poor starting candidates include decisions whose meaning is disputed, tasks with no reliable evidence and high-consequence approvals without independent safeguards. Before comparing models, use our AI readiness checklist to agree the task and the acceptable outcome.
Type-safe does not mean factually correct
A type-safe response respects the allowed structure. If the options are billing, technical support and review, the system should return an allowed value rather than invent a fourth department. That is an interface property.
It can still choose the wrong allowed department. A validly structured decision can be based on incomplete evidence, a poorly written question or a mistaken interpretation. Schema correctness and real-world correctness are separate tests.
This distinction matters because the launch material uses broad language about hallucination. For a business implementation, the defensible interpretation is narrower: preventing an out-of-schema answer does not prove that every judgment is true. Validate the meaning of the output against the evidence and the intended behaviour.
There is a similar limit to verification models. A model used to check another model is another fallible component. It can be useful, but agreement between them is not independent proof that a claim is correct.
What is the difference between probability and confidence?
According to TypeSafe's current documentation, Choice and Score responses include a distribution of probabilities across the available options or levels. Their confidence value summarises how concentrated that distribution is. A clear preference for one option produces a different signal from a distribution spread across several plausible options.
Confidence is therefore not a universal probability that the entire workflow is correct. It says nothing by itself about whether the input record belongs to the right customer, whether the source is current or whether the requested action is authorised.
The distinction is even more important for Noul questions, which return a probability for a yes/no condition and do not carry the same separate confidence property. A probability near the middle indicates uncertainty between yes and no, not a medium amount of the condition being measured.
Calibration is about how probabilities relate to observed outcomes across comparable cases. In an illustrative group of 100 predictions assigned a 90% probability, roughly 90 correct outcomes would be consistent with calibration at that level. It does not tell you which individual predictions will be wrong, and a small test group cannot establish general reliability.
A worked example: suggest a support queue
Illustrative design, not a deployed customer case: a business receives free-text support requests and wants staff to spend less time sorting them. The initial system recommends a queue while a person remains responsible for confirming the handover.
The input could contain the message, a maintained description of each support queue and only the account context necessary for routing. Keep passwords, payment credentials and unrelated customer history out of the request.
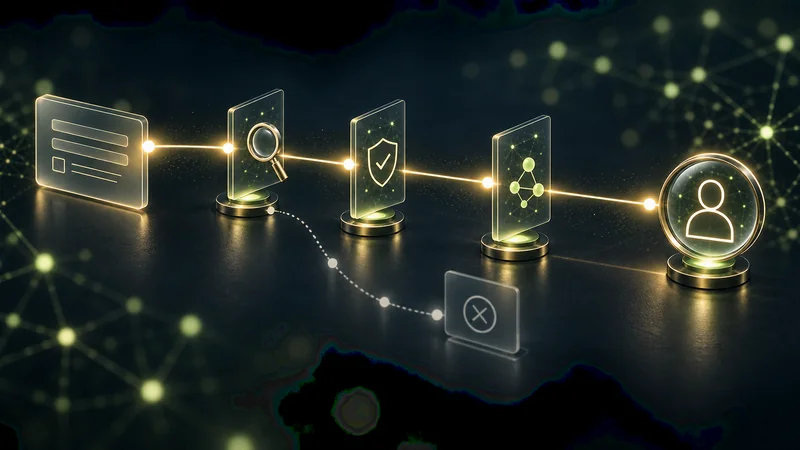
Break the work into explicit judgments:
- Does the message contain enough information to suggest a route?
- Which approved queue best matches the request?
- Does it contain an urgency condition defined by the business?
- Does it require a specialist or human exception route?
Some judgments can be requested together when they use the same evidence and do not depend on one another. The application should use only the relevant answers. TypeSafe's building guide explains this pattern of small judgments composed by code.
A message saying “I was billed twice and cannot log in” also exposes a design choice: must it have one primary owner, or can it carry several issue labels? Define that policy before choosing a single-choice question. One neat answer is not helpful if the actual request has two legitimate needs.
In the first pilot, store the suggestion and the staff member's confirmed route. Do not silently close tickets, send promises to customers or change commercial status. Routing a message is not the same as qualifying a lead; those definitions belong in a separate enquiry-measurement process.
How should you choose an automation threshold?
Do not copy a confidence threshold from a demonstration and call it safe. The appropriate boundary depends on the task, the cost of a mistake and how the model performs on your data.
Begin in recommendation-only mode. Compare suggestions with reviewed outcomes, inspect mistakes and check whether high-confidence errors still occur. Evaluate both normal cases and the cases that should stop: missing information, mixed requests, unfamiliar terminology and contradictory records.
Then decide which low-consequence actions, if any, may proceed automatically. Keep permissions independent. A confident classification of “refund request” does not authorise a refund; it may only route the request to the person who can assess it.
Monitor performance after changes to the model, question wording, category definitions or incoming message mix. A threshold evaluated on one configuration is not automatically suitable for another. Retain a way to return to manual routing without losing requests.
What did developers ask on Hacker News?
The Jev launch discussion contained enthusiasm about a non-chat interface, questions about its mechanism and scepticism about the comparisons. That mixture is more useful than describing the launch as universally acclaimed.
In one comment, big_toast pointed readers towards the documentation and discussed the state, question types and returned probabilities. Other participants proposed possible applications. Those suggestions show what people wanted to explore, not what has been proven in production.
The business lesson is to inspect the interface and the evaluation design, not just the headline. Does the proposed task fit the available questions? Is the comparison against a sensible alternative? Are the expected answers independently reviewed, or merely supplied by another model?
Hacker News is a developer discussion forum, not a representative customer survey or an independent certification of reliability.
What should a meaningful pilot measure?
Compare the whole workflow with the simplest credible alternative: existing rules, manual handling or the current model-based process. Keep the same test cases and decision definitions across the comparison.
Record correct routes, wrong routes, requests sent to review and unresolved cases. Inspect performance by category rather than hiding a weak but important category inside an overall accuracy figure. Count the time people spend correcting the suggestions.
For uncertainty, compare observed outcomes across probability ranges and inspect confident mistakes. For operations, measure the complete request-to-result time, including network delay, retries and application work. TypeSafe notes that its published latency evaluations are generally run from the US West Coast, where its service is based; that is not a latency measurement from South Africa.
Include all material costs: model calls, repeated attempts, monitoring, integration and human review. A cheap classification call can be worthwhile, but it does not make the surrounding process free. Also test service failure. An unavailable model should send the request to a known fallback, not make the enquiry disappear.
Use the model for a judgment and keep the workflow in code. Jev is a concrete example of a promising interface for business automation. Whether it is the right component depends on evidence from the decision you actually need to make.
Discuss a specific automation decision with Digital 4 Jesus. Bring sample inputs you are authorised to share, the allowed outcomes and what should happen when the system is uncertain.